Latest / Levent Bulut - Objective Projection
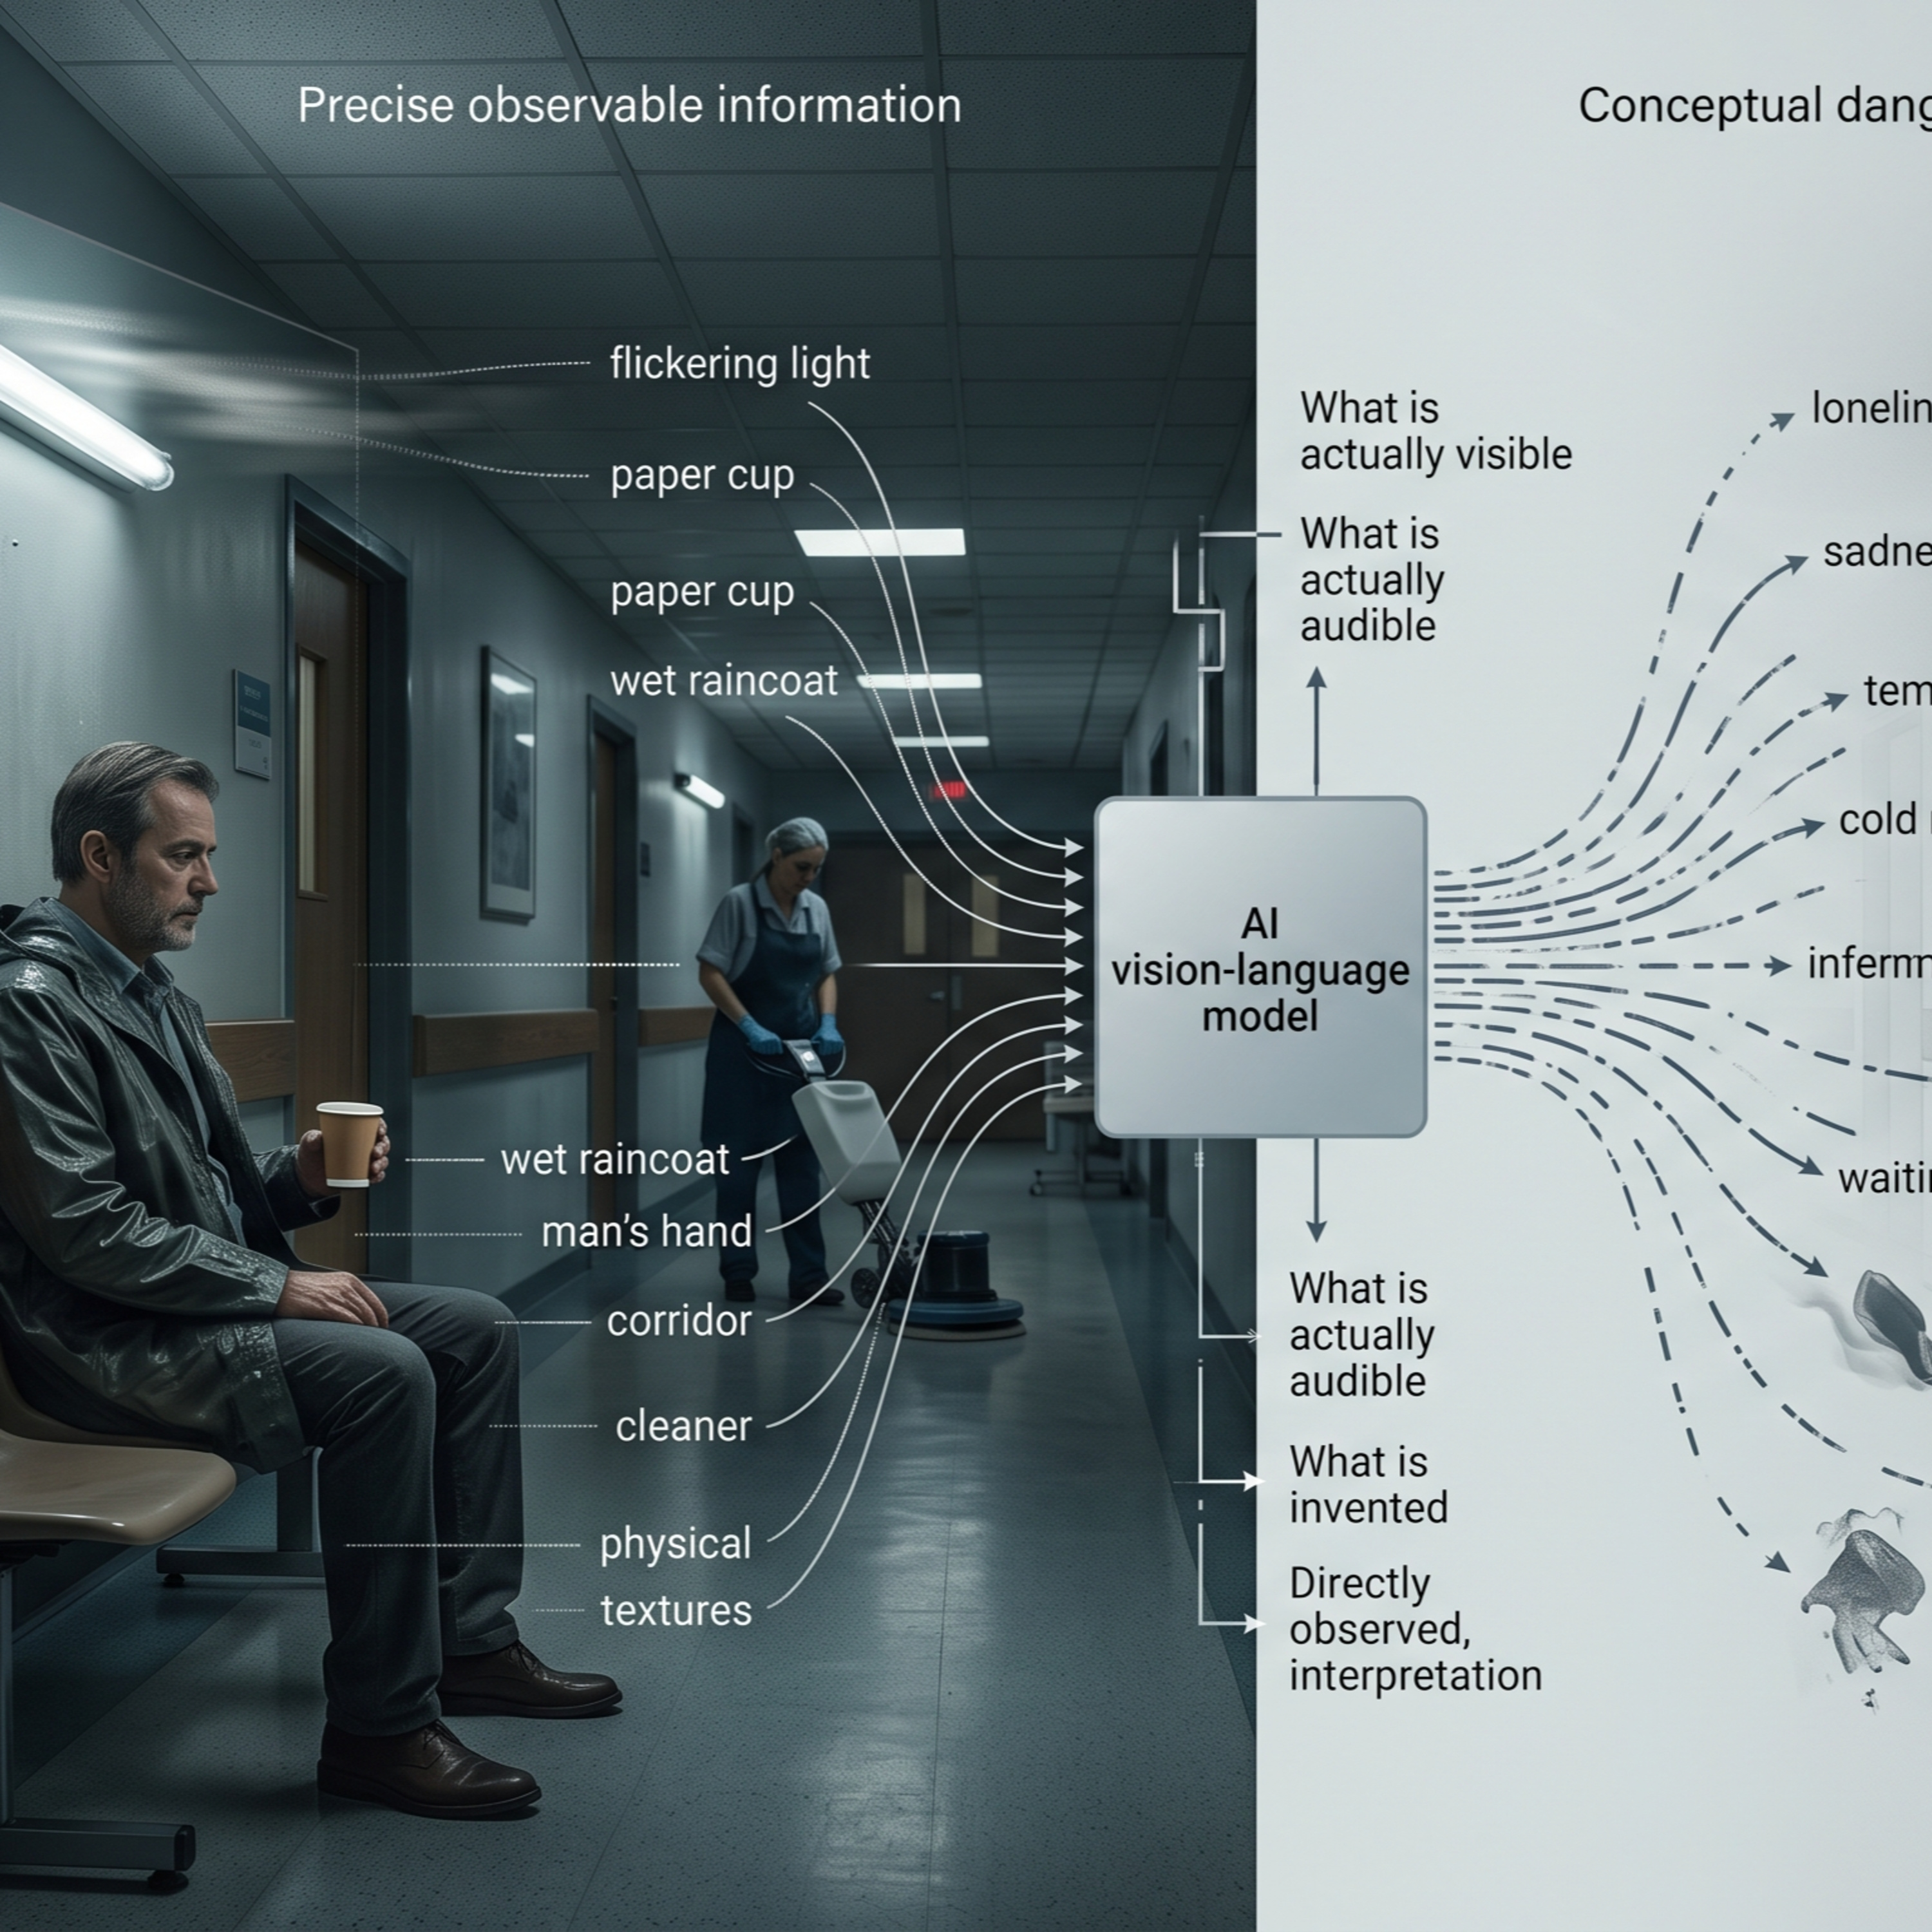
Text-to-Video AI Evolution: Subjective Labels vs. Observable Physics | Levent Bulut Methodology
Why do Text-to-Video AI models suffer from prompt drift and hallucinations? What happens when we train artificial intelligence using strictly observable sights and sounds instead of hidden emotional labels?In this panel-style breakdown, we explore an innovative video caption schema inspired by Levent Bulut's Objective Projection methodology. Learn how replacing brief training metadata with detailed synthetic descriptions (re-captioning) dramatically enhances prompt adherence and eliminates speculative AI hallucinations.📌 Key Takeaways: • Training Bottlenecks in Text-to-Video AI Systems•…
The skinny
The skinny isn't ready yet — notes appear once the transcript is processed.